

The trust problem
Business decisions run on metrics. Revenue per market, customer acquisition rates, trade volumes, conversion funnels. Every morning someone opens a dashboard and makes a call based on what the numbers say.
But what if the numbers are wrong?
The uncomfortable truth is that data quality in many companies rests on hope. The guardrails are fragile. Somewhere downstream a stakeholder might notice that a chart looks a bit off. Maybe they mention it in a meeting. Maybe they send a Slack message to the data team. Maybe nobody notices until a quarterly review when someone asks why the trend shifted in March and the answer turns out to be a bug that has been producing bad data for weeks.
This is how it works at many places. Not because people are careless but because the alternative has been expensive or complicated. Building proper automated monitoring for every metric means custom SQL, custom alert rules, custom maintenance per metric. The overhead is real and it does not scale. So you end up monitoring the three most critical metrics and hoping for the best on everything else.
I think there is a better way. Not a massive platform project but a lightweight framework that plugs into what you already have. If you run dbt on BigQuery you can set this up in an afternoon.
What good guardrails look like
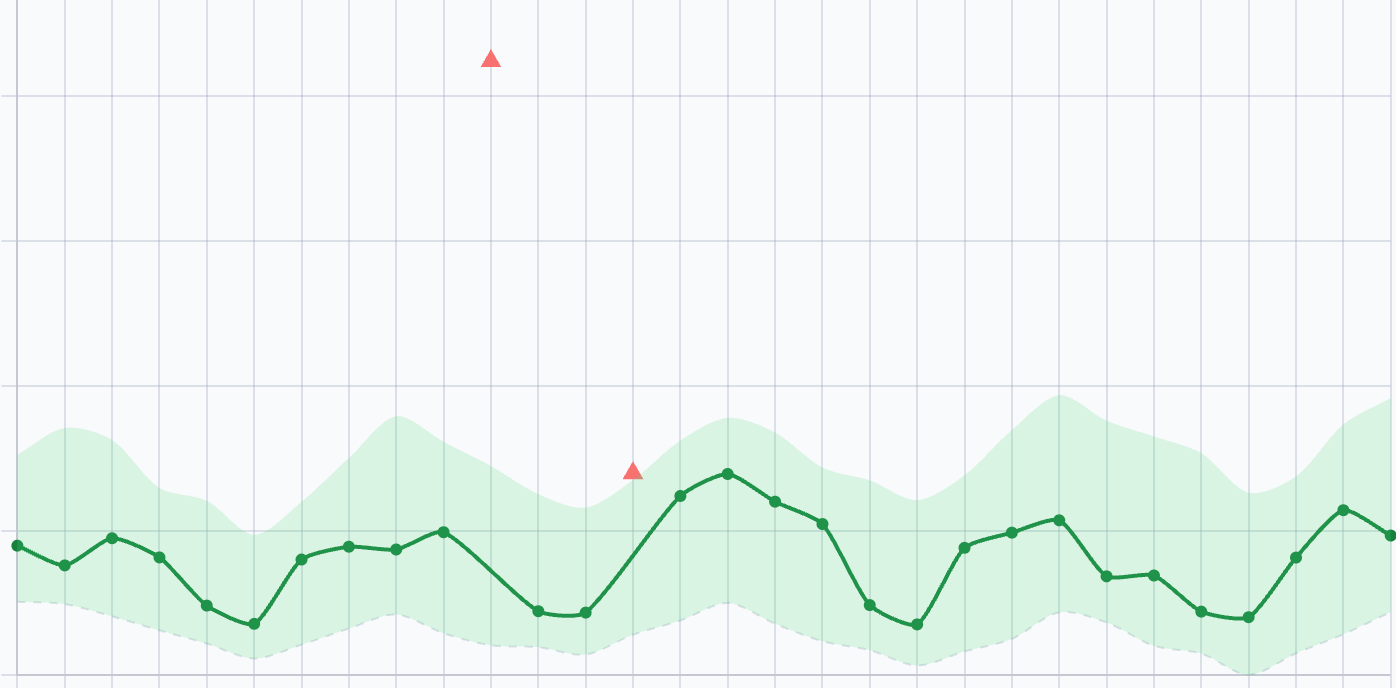
Before jumping into the solution it is worth thinking about what we actually want. The initial goal is not to build an alerting system that pages someone at 3am. The goal is to catch data quality issues earlier and reduce the dependency on someone happening to look at the right dashboard at the right time.
Good guardrails should:
Adapt automatically. Static thresholds break. A number that is normal in January is suspicious in July. The system needs to learn the patterns on its own.
Work per segment. A 30% drop in one country can hide inside a healthy aggregate. Detection needs to happen at the level where problems actually occur.
Scale without effort. Adding the tenth metric should be as easy as adding the second. If every new metric is a project then adoption dies.
Stay out of the way. This should not add complexity to your core pipelines. If the anomaly detection breaks it should not take anything else down with it.
The approach
I built a framework that does this using two things that were already in our stack: dbt and BigQuery ML. The idea is simple. Each metric you want to monitor is a small SQL file that outputs 4 standardized columns. All metrics feed into a shared timeline table. Then a single BigQuery ML call runs anomaly detection across everything at once.
metric SQL files  -->  unified timeline  -->  anomaly detection
  (ephemeral)            (table)              (incremental)
I prototyped this during a hackday at Nordnet with some help from Claude. The whole thing took about 2 hours including a first test metric and validation. It is intentionally lightweight because I think the biggest risk with this kind of project is over-engineering it into something nobody wants to maintain.
The output contract
The foundation is a 4-column contract that every metric model follows:
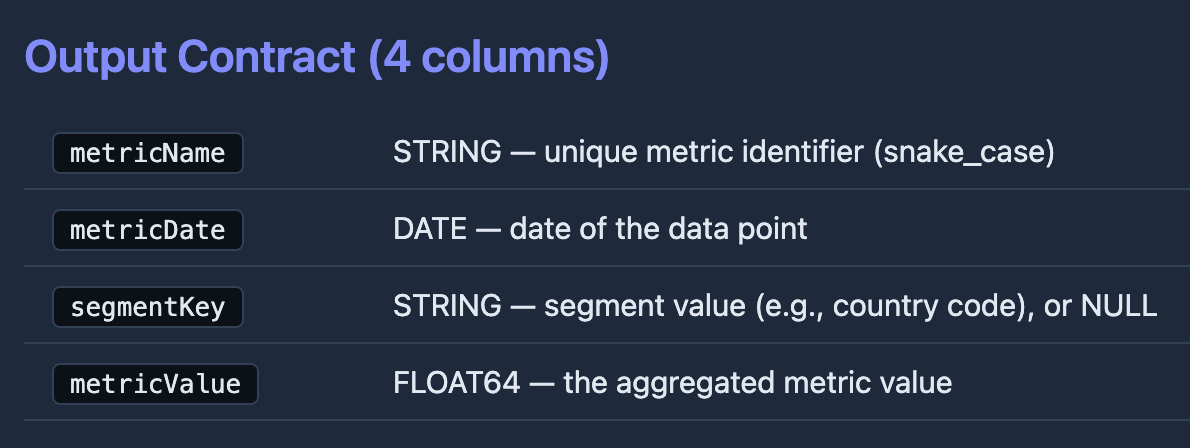
This is small on purpose. The SQL inside each metric file can be as complex as you need. Joins, window functions, conditional aggregations. The framework does not care how you calculate the number. It only needs the result in this shape.
A simple metric looks like this:
SELECT
  'new_customers_daily' AS metricName,
  CAST(validFromDate AS DATE) AS metricDate,
  CAST(countryCode AS STRING) AS segmentKey,
  CAST(COUNT(*) AS FLOAT64) AS metricValue
FROM {{ ref('customers_v1') }}
WHERE
  validFromDate >= DATE_SUB(CURRENT_DATE(), INTERVAL 90 DAY) AND
  validFromDate < CURRENT_DATE()
GROUP BY ALL
A more complex one with filters and multi-segment keys works exactly the same way:
SELECT
  'daily_revenue' AS metricName,
  CAST(accountingDate AS DATE) AS metricDate,
  CAST(market || '|' || channel AS STRING) AS segmentKey,
  CAST(SUM(totalRevenue) AS FLOAT64) AS metricValue
FROM {{ ref('revenuePerAccount') }}
WHERE
  accountingDate >= DATE_SUB(CURRENT_DATE(), INTERVAL 90 DAY) AND
  accountingDate < CURRENT_DATE() AND
  transactionType != 'INTERNAL'
GROUP BY ALL
Same 4 columns out. Same detection pipeline. The complexity stays inside each metric file where it belongs.
How it fits together
Metric models
Each metric is a dbt model set to ephemeral meaning it does not create a table. The SQL gets inlined into the timeline at compile time. No warehouse clutter and no extra scheduling.
The YAML file next to each metric carries the anomaly detection config in the meta block:
models:
  - name: governance_metricNewCustomersDaily
    description: >
      Daily new customer count per country.
    config:
      materialized: ephemeral
      meta:
        team: team-crm
        domain: marketing
        metricName: new_customers_daily
        anomalyThreshold: 0.95
        businessOwner: alice@example.com
        technicalOwner: bob@example.com
Threshold and owners live right next to the metric definition. One metric, one place to look.
The timeline
All metrics get unioned into a single table:
SELECT * FROM {{ ref('governance_metricNewCustomersDaily') }}

UNION ALL
SELECT * FROM {{ ref('governance_metricDailyRevenue') }}
Every metric is an explicit ref() call so dbt has full visibility into the dependency graph. The table rebuilds daily with 90 days of history. This becomes the training data.
Anomaly detection
The detection model reads config from each metric’s YAML at compile time using dbt’s graph.nodes. Then it makes a single AI.DETECT_ANOMALIES call with all metrics and segments together:
SELECT *
FROM AI.DETECT_ANOMALIES(
  (SELECT metricName, segmentKey, metricDate, metricValue
   FROM TimelineData WHERE metricDate < start_date),
  (SELECT metricName, segmentKey, metricDate, metricValue
   FROM TimelineData WHERE metricDate >= start_date),
  id_cols => ['metricName', 'segmentKey'],
  data_col => 'metricValue',
  timestamp_col => 'metricDate',
  model => 'TimesFM 2.5',
  anomaly_prob_threshold => 0.95
)
The id_cols parameter tells TimesFM that each combination of metric and segment is its own time series. So new_customers_daily + SWEDEN and new_customers_daily + NORWAY are independent series but processed in one call. One API invocation instead of N.
After the AI call it joins back per-metric thresholds and owner emails. The result is an incremental table that grows one day at a time. It can feed a dashboard, trigger alerts or just sit there for the data team to check each morning.
Why TimesFM matters for this
The reason this approach is viable is TimesFM. It is Google’s pre-trained time series foundation model built natively into BigQuery. The key property is that it needs no training. You do not create a model object, manage storage, tune hyperparameters or schedule retraining. You pass in data and get anomaly probabilities back.
This matters more than it sounds. With traditional approaches like ARIMA you would need to train and maintain a model per time series. If you have 20 metrics across 4 segments that is 80 models to manage. The ML ops overhead alone would make a config-driven framework impractical.
With TimesFM the cost of adding a new metric is just the SQL file and the YAML config. Zero ML ops work. That is what makes it possible to say adding a metric takes 3 steps and actually mean it.
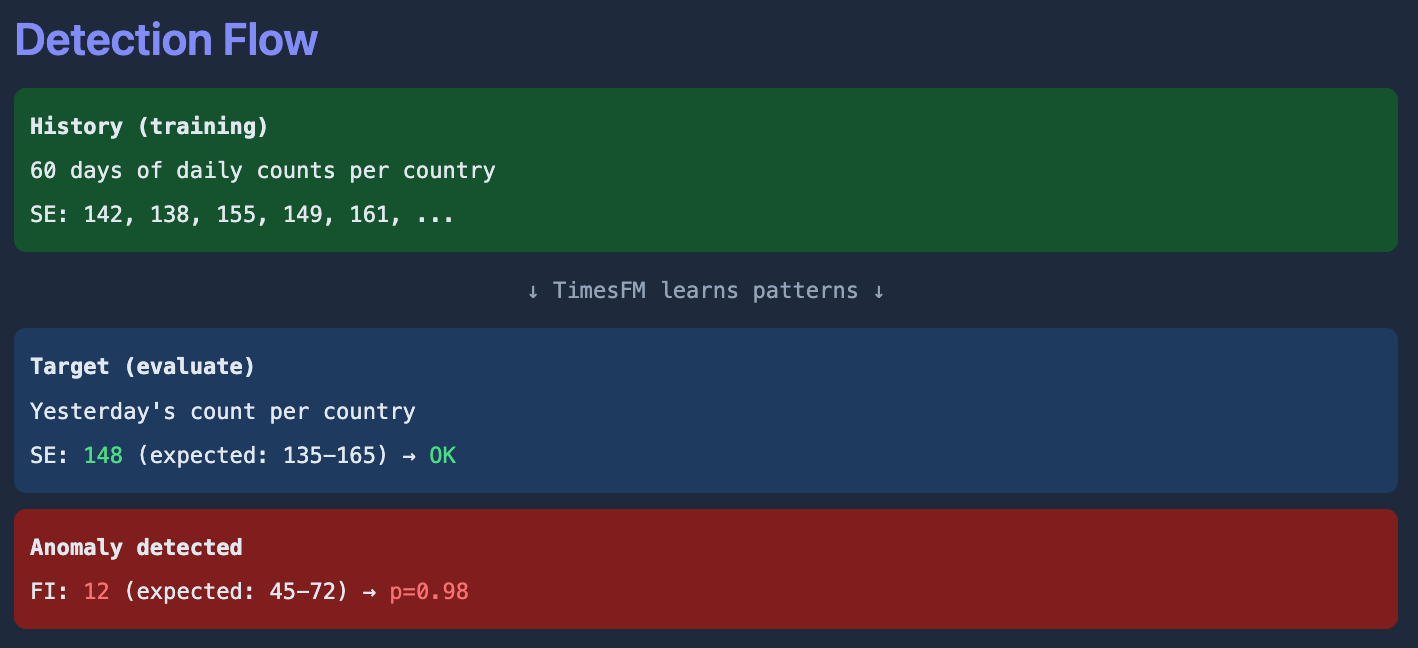
For each data point TimesFM returns an anomaly probability between 0 and 1 plus expected lower and upper bounds. We compare the probability against each metric’s own threshold to decide if something gets flagged. Different metrics can have different sensitivity. A 0.99 threshold for revenue means you only flag high-confidence deviations. A 0.90 for operational metrics gives you earlier warnings.
First test
I ran the framework against a single metric across four Nordic markets using a 0.95 threshold and 90 days of history. It successfully flagged anomalies in all four segments while normal daily variance was left alone.
What stood out is that TimesFM learned each segment’s baseline independently without any configuration. Different markets had different scales and different patterns and it handled all of them automatically.
Worth noting that an anomaly does not have to mean something is broken. It could be a data quality issue but it could also be the result of a marketing campaign, a competitor doing something unexpected or just a public holiday. The point is not to say this is wrong but to say this is unusual, you might want to look at it. Either way it is probably worth investigating rather than letting it pass unnoticed.
The test also showed where the framework needs more work. Several of the flagged anomalies were holiday-related and could be suppressed with a public holiday calendar. That is a known pattern from our data volume anomaly detection and straightforward to add (read previous post).
Adding a new metric
Three steps:
Write a SQL file that outputs the 4 contract columns
Create a YAML file with the anomaly config in meta
Add a UNION ALL line to the timeline
No config tables. No seeds. No framework changes. The next scheduled run picks it up automatically.
To make this even more accessible I wrote a Claude Code skill that automates these steps. You describe the metric in plain language and it generates the SQL, the YAML and the timeline edit. I validated it by deleting the PoC metric and asking Claude Code to recreate it from the same requirements. The output was identical to the original. Let me know if you want me to share the skill too (it is too long to embedding it in the post)
Design decisions
A few choices worth explaining.
Why individual SQL files instead of a config table? My first attempt was a CSV where you configure source table, aggregation function and segments. A macro generates the SQL. This works for simple metrics but falls apart for anything that needs joins or conditional logic. You keep adding columns to the config trying to cover every case. The contract-based approach is simpler. You write whatever SQL you need and just follow the output shape.
Why not a seed table for thresholds? Seeds require a separate dbt seed step and split the metric definition across files. Putting the config in the YAML meta keeps everything about a metric in one place. The detection model reads it at compile time via graph.nodes. The trade-off is you need an execute guard for linter compatibility and custom meta fields may trigger IDE warnings. Both are minor.
Why ephemeral models? No intermediate tables, no extra scheduling. The timeline build automatically includes everything. The trade-off is you cannot query a metric model on its own for debugging. If you need to you can temporarily change the materialization to table.
Why one TimesFM call? BigQuery ML has per-invocation overhead. One call with id_cols to separate the series is cheaper, simpler and easier to reason about than 40 separate calls.
What comes next
This is a proof of concept. The gap between this and production is mostly about reducing noise and making the output actionable.
Short term. Holiday suppression using public holiday calendars. Alert severity levels based on how many consecutive days are anomalous. More metrics to validate that the approach works across different data patterns and scales.
Medium term. A dashboard for browsing anomalies filtered by metric and segment and severity. Automated notifications routed to the right owners. Significance filters so you do not get alerted about a 200% spike on 3 rows. An override mechanism for known events like planned migrations or seasonal campaigns.
Longer term. An AI agent that picks up flagged anomalies and tries to figure out what caused them. It could check if there was a deployment that day, look at related metrics to see if the pattern is isolated or widespread, cross-reference with a holiday calendar or check if a marketing campaign was running. The goal would be to hand the data team a short summary like this is likely caused by X or this looks like a real issue, here is what else is affected instead of just a raw flag. That would close the loop from detection to investigation and save a lot of manual digging.
The bigger picture
The technical implementation is not that complicated. A few SQL files, some YAML config and one BigQuery ML call. What makes it interesting is what it changes about how you operate.
Many data teams today rely on downstream consumers to be the quality check. A stakeholder notices something looks wrong. They ask the data team. The data team investigates. Maybe they find a broken pipeline. Maybe it was a real business change. Either way the detection happened by accident and the feedback loop was slow.
With automated anomaly detection on your key metrics you shift from reactive to proactive. The system checks every metric every day (or frequency configured in YAML) and flags what looks unusual. The data team reviews the flags in the morning instead of waiting for someone to complain. Issues get caught in hours instead of weeks.
And because the framework scales easily you can go beyond the top 3 critical metrics. You can monitor the long tail of metrics that nobody has time to watch manually. The ones where a silent failure can go unnoticed for months because they are not on anyone’s daily dashboard.
This is not about building a perfect anomaly detection system. It is about raising the floor. Making the baseline level of monitoring good enough that the obvious problems get caught automatically so humans can focus on the subtle ones.
What is your experience?
How do you monitor your business metrics for anomalies today? Mostly dashboard watching or do you have something automated?
Where do you draw the line between anomaly detection and alerting? Should the data team own this or should metric owners self-serve?
Do you think an AI agent could realistically triage anomalies on its own or does it always need a human in the loop?
How do you handle the false positive problem? Holiday suppression helps but what else has worked for you?
Disclaimer: I’m Robert Sahlin, founder of Supercargo. We help companies build modern data platforms on Google Cloud using agentic coding and platform engineering. If you are interested in setting up something like this or want help with your data platform in general, we offer both consulting services and product. Get in touch at hello@supercargo.dev
I would just pick use dbt Elementary (https://docs.elementary-data.com/home) and be done with it. It is a lot more dbt native and working with many DWH (including BigQuery) and also collecting metadata for alerting & data observability at scale. The integration would just be YAML files mostly